LangChain Command Center
Five agent-pattern diagrams on one page. A run calls Claude, and the console stays unconfigured until an API key is supplied.
The idea
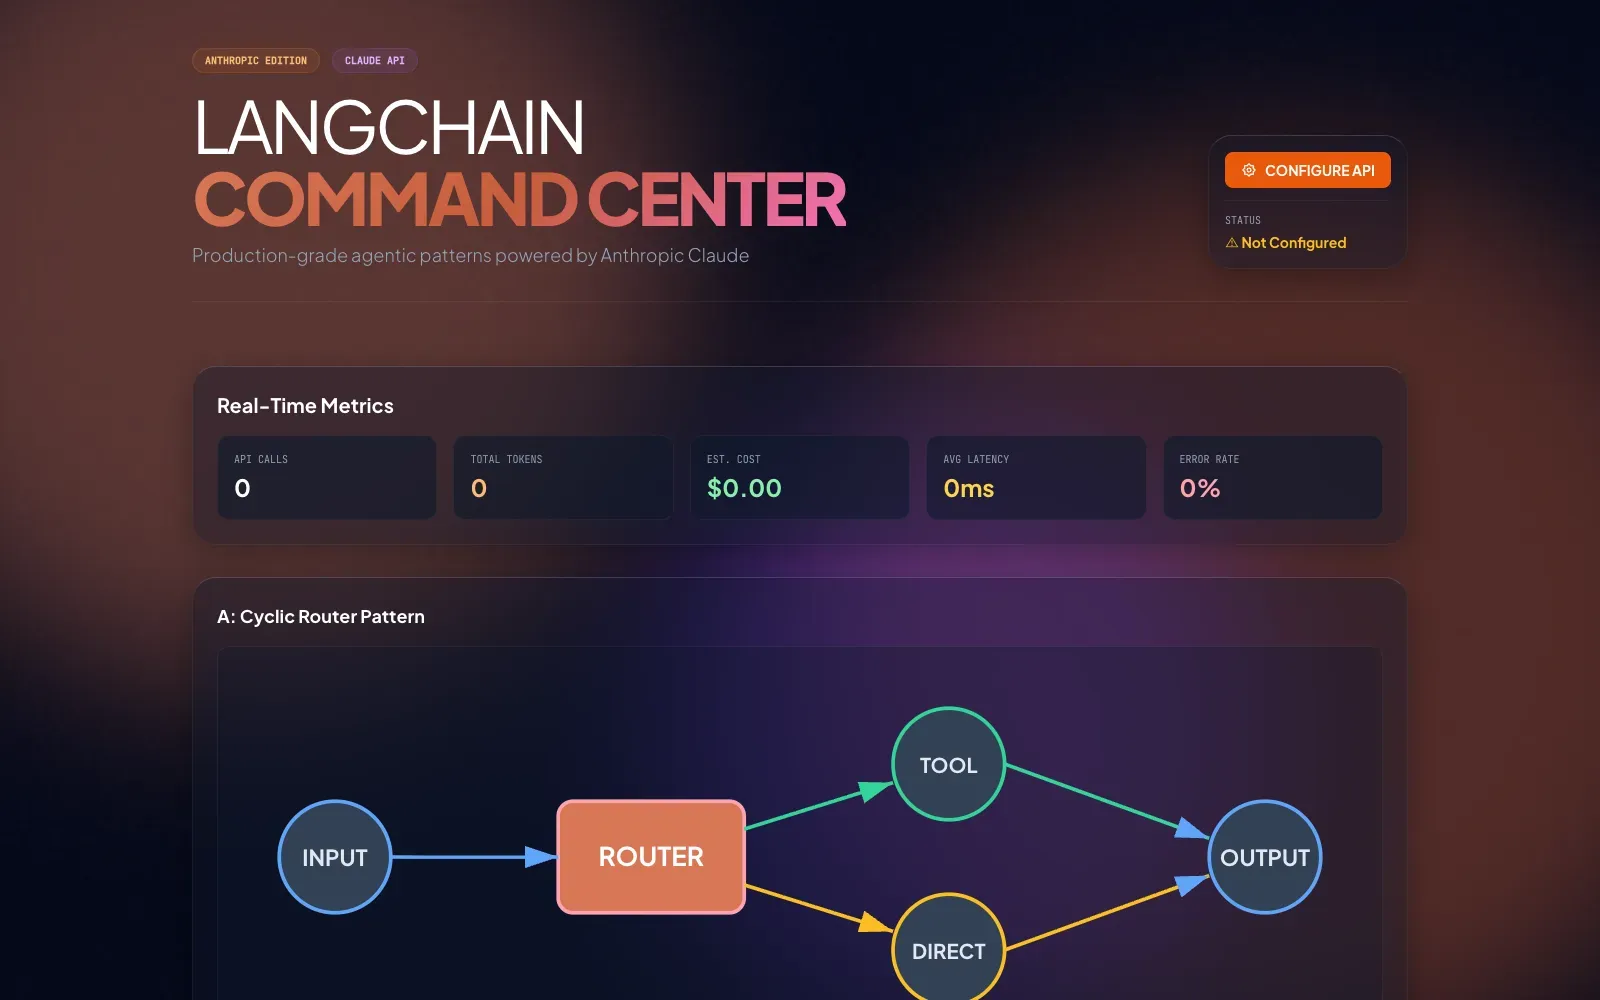
LangChain Command Center is a static page of five diagrams, labelled A to E. The diagrams are the patterns. A run button under each one calls Anthropic's messages API. Until a key is saved, the status reads ⚠ Not Configured, and a run ends with the error API key not configured.
The approach
The header carries two badges, ANTHROPIC EDITION in orange and CLAUDE API in purple, plus CONFIGURE API. Status underneath is amber while it reads ⚠ Not Configured, and green once it reads ✓ Configured. The key is kept in the browser's local storage. Settings offer Claude 3.5 Sonnet, Claude 3.5 Haiku or Claude 3 Opus, and a max-token field that opens at 1024, between 1 and 4096. The page ships without a key.
Real-Time Metrics sits above the patterns and starts at zero: API Calls, Total Tokens in orange, Est. Cost in green, Avg Latency in amber, Error Rate in rose. The cost figure averages the selected model's input and output prices and multiplies by the tokens the API reports.
A, Cyclic Router Pattern, draws INPUT, an orange ROUTER, a green TOOL circle and an amber DIRECT circle, both arrows running on into OUTPUT. The line under the figure reads Classification → Conditional branching → Response. A run is one call: the model is asked to choose TOOL or DIRECT and then answer.
B, Supervisor Pattern, draws a teal SUPERVISOR with dashed purple arrows to AGENT-1, AGENT-2 and AGENT-3, then solid teal arrows into RESULT. The caption reads Central orchestration → Parallel delegation → Aggregation. A run is one call in which the model is asked to describe a delegation and then give the result.
C, Multi-Agent Debate, puts TOPIC at the top, rose AGENT-A and AGENT-B either side of an amber JUDGE, and a green VERDICT below. Dashed amber arrows run back from the judge towards the two agents. The boxes underneath are AGENT A, JUDGE and AGENT B. A run is three calls: one for the topic, one against it, then a verdict.
D, RAG Pipeline, runs QUERY into a green RETRIEVER, with a dashed link up to a box labelled VECTOR DB, then CONTEXT AUGMENT, a green GENERATOR and RESPONSE. A small label on the figure says Docs + Query. The run asks the model to simulate that retrieval and then answer.
E, Meta-Cognitive Loop, runs INPUT through a purple INITIAL RESPONSE, an amber SELF CRITIQUE and a purple REFINED RESPONSE. A dashed rose arrow loops back, and a green box reads QUALITY CHECK. The caption reads Generate → Self-evaluate → Refine → Verify loop. The three boxes underneath are INITIAL, CRITIQUE and REFINED, filled by three successive calls.
Execution Traces starts as No traces yet. Each line is a time, a pattern name in brackets, and a status. CLEAR wipes the list, which keeps the latest 20 lines.
- Status opens at ⚠ Not Configured; the key stays in the browser
- Router: orange ROUTER, green TOOL, amber DIRECT; supervisor fans out to AGENT-1, AGENT-2 and AGENT-3
- Debate is three calls; the meta-cognitive loop fills INITIAL, CRITIQUE and REFINED
- Models on offer: Claude 3.5 Sonnet, Claude 3.5 Haiku, Claude 3 Opus; max tokens open at 1024
Play the current build: /simulations/langchain-command-center .